AI Aggregates: How Aggregated Intelligence Turns Scattered Data Into Real Decisions
AI aggregates combine multiple models, data sources, and signals into one usable answer. Learn how aggregation works, which patterns to use, and how to build it.

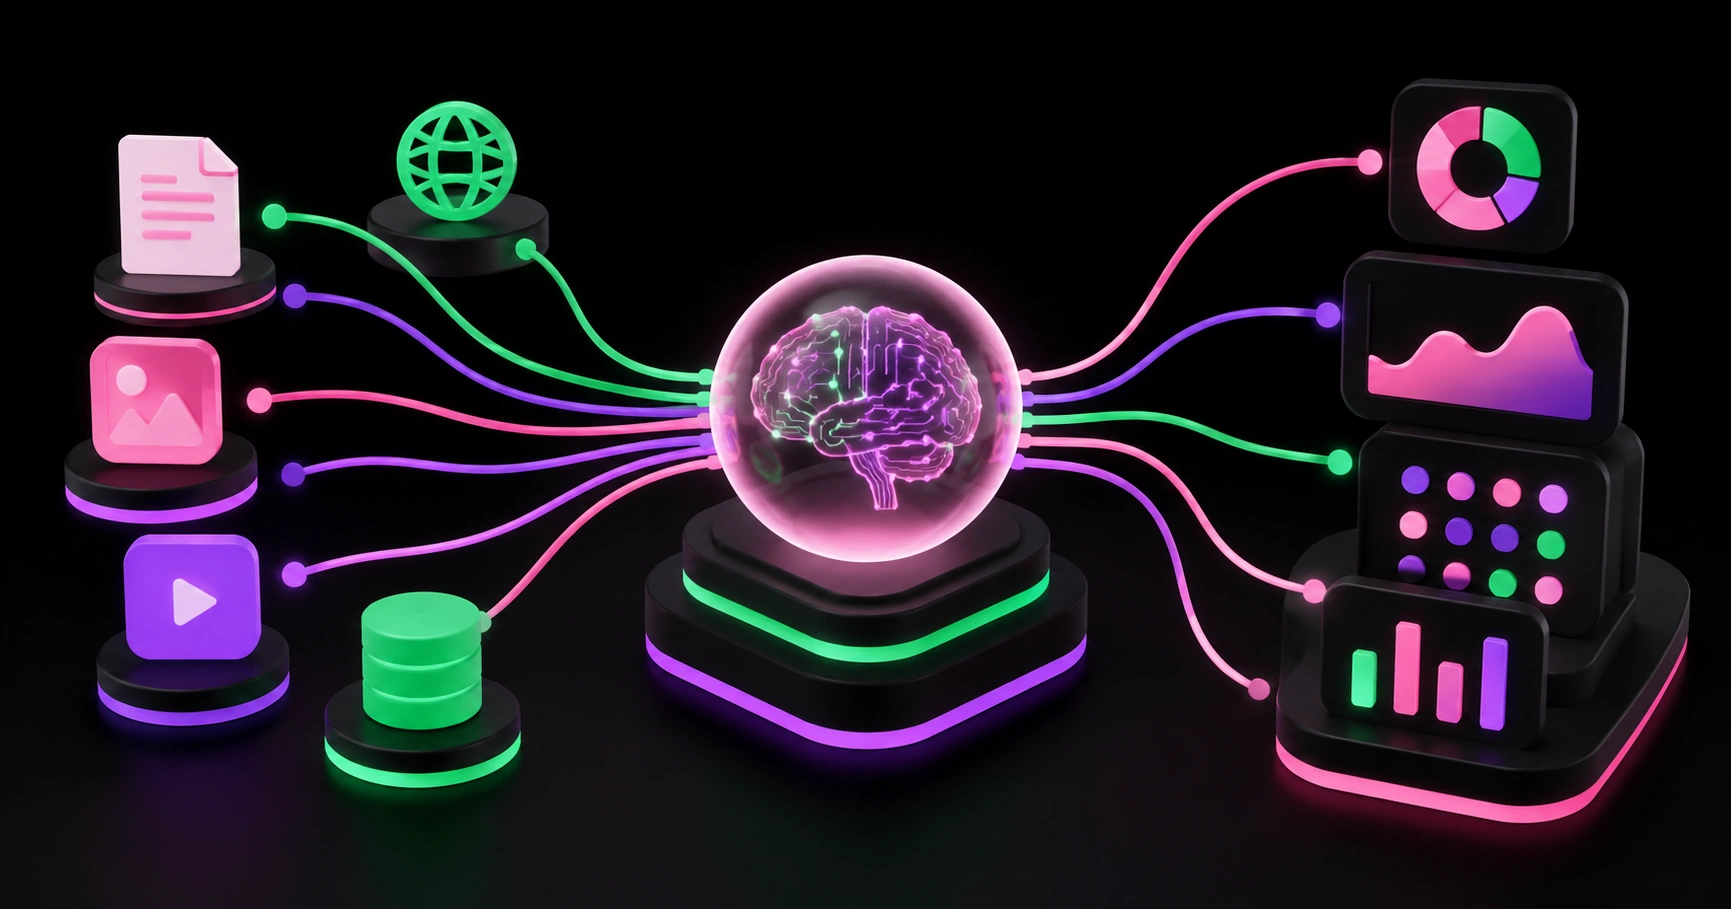
An AI aggregate is any system that combines multiple inputs — several models, several data sources, or many individual records — into a single summarized output that a human or another system can act on. The term shows up in three very different contexts, and confusing them is the most common reason aggregation projects stall. It can mean data aggregation performed by AI (rolling thousands of reviews into one sentiment score), model aggregation (routing a request across several models and merging or picking the best result), or aggregate reporting (dashboards where AI compresses raw events into metrics). Each version has different infrastructure, different failure modes, and a different definition of "correct." This guide separates them, then shows exactly how to build an aggregation layer that survives contact with production data.
Quick Answer: AI aggregates are systems that merge many inputs into one trustworthy output. They appear as data aggregation (AI summarizing many records), model aggregation (combining or routing between multiple models), and metric aggregation (AI-generated rollups in reporting). The hard part is not the merging — it is preserving traceability back to every source that produced the answer.
Where WebPeak Fits Into an AI Aggregation Project
Aggregation work usually fails at the seams: the data pipeline exists, the model exists, but nothing joins them to a working interface that a non-technical team can trust. That integration layer — ingestion, normalization, model orchestration, and a front end that exposes provenance — is where the team at WebPeak tends to be brought in, since a single group handles both the AI implementation and model orchestration side and the . Their teams work with clients worldwide, which matters here for a practical reason: aggregated datasets frequently span regions with different data-residency rules, and the aggregation design has to account for that before ingestion begins, not after.